

What this work covers, and what it leaves alone
Aranv helps you train an LLM on your codebase when retrieval over your repositories stops being enough: a large language model (LLM) tuned on reviewed, merged code, checked for secrets and licenses, tested on your real merged changes and run where your code can stay, with your reviewers still in place.
Start with what nearly every team should try: retrieval over the repository, clear instructions and a strong model, chosen with help from our AI model comparison. Training your own AI model is a later step, because code changes daily and weights do not. When it is justified we tune open-weight base weights; training from zero is rarely sensible.
Tests come from your own history. Training uses changes merged before a chosen date, and the exam replays later merged changes from the state just before each one. Cherry-picks and backports are removed, since they would leak answers. Output must compile and pass your test suite, and then engineers grade it.
Why most teams should try the simple route first
From repository search to a trained code model
- 01 Index the repository Retrieval plus written instructions give a good model your code as context.
- 02 Replay real merged changes Past issues are replayed to show what the simple setup gets wrong.
- 03 Clean the training set Secrets, vendored code and license problems are found before any training.
- 04 Tune only if justified A tuned model must beat the baseline on changes it never saw.
Many teams stop after the second step, because retrieval and good instructions pass.
What a custom code model can add
With your repository as context, a model can usually read your code. Training is for habits it still gets wrong.
-
Internal framework calls
Completions use your in-house libraries and patterns that public models never saw, instead of a popular public package you do not use.
-
Repeatable migration edits
Past migration pull requests teach the pattern for moving call sites off an old library, producing draft changes an engineer completes.
-
Review notes in your rules
Trained on past review comments, the model raises the points your senior engineers keep repeating, before a person opens the pull request.
-
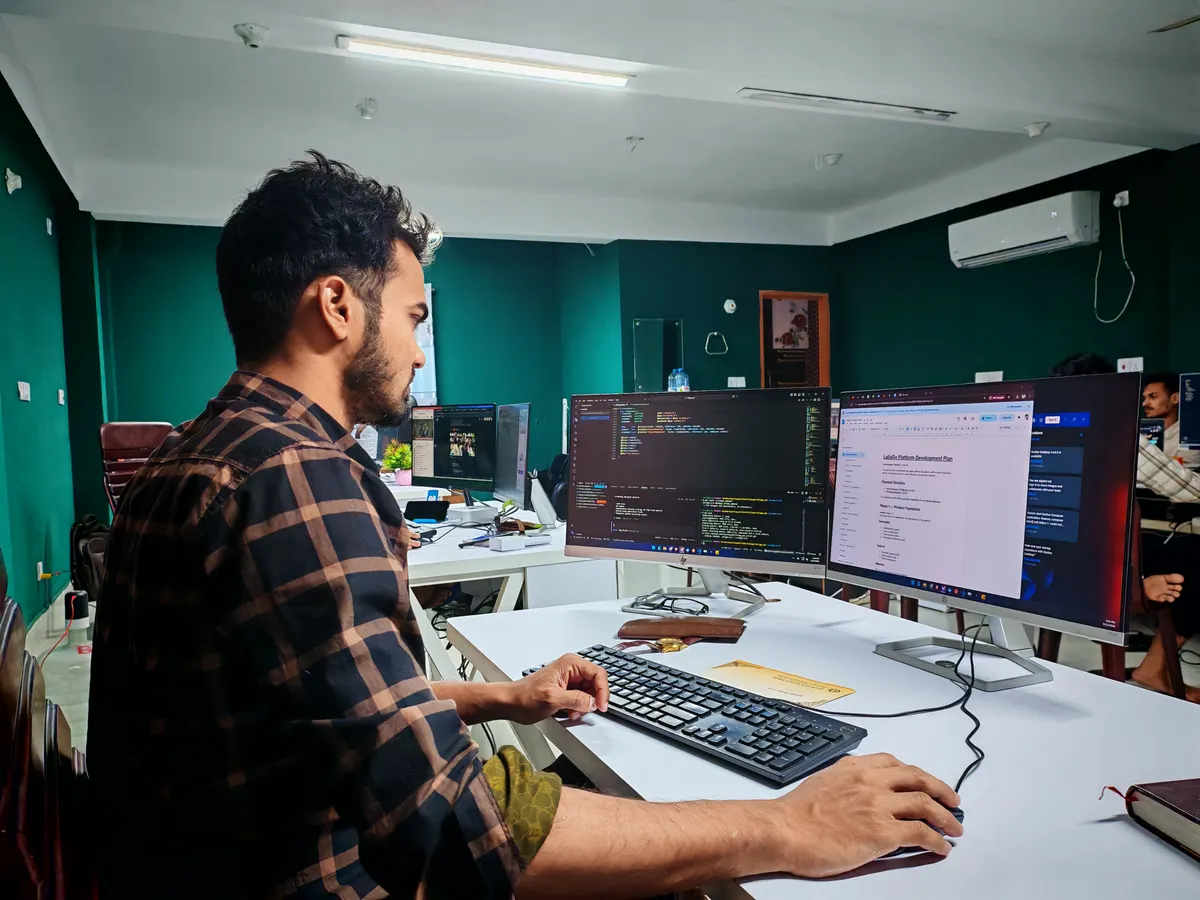
Code that cannot leave
For repositories that must stay in your network, a tuned model and its editor integration run on your own servers, alongside retrieval.
When training fits, and when it does not
Training fits three situations: a large private codebase, internal frameworks that public models do not know, or code that cannot leave your control. If your stack is mostly public frameworks, retrieval over the repository plus a good instructions file will probably serve you better, with less upkeep.
What we do
- Repository and framework review
- Retrieval baseline on real issues
- Written train or do-not-train recommendation
- Upkeep plan as the code changes
Cleaning a codebase before it trains anything
Models can repeat what they see. A key committed years ago and later removed still sits in history, and vendored code may carry license terms you cannot redistribute. We scan the training set, exclude generated files and retired patterns, then plant fake secrets to test whether they come back.
What we do
- Secret scanning across git history
- License checks on vendored code
- Generated and minified files excluded
- Planted canary strings in the tests
How we approach a project
The Stack Overflow 2026 survey shows these tools are in daily use, so review matters more. Branch protection, code owners and required approvals stay as they are. If AI-written code has already caused trouble, see vibe coding rescue.
When code cannot leave, private deployment covers the servers. Wider work sits under AI software development. Your code is used for your model. To compare options for your repositories, set up a 30-minute conversation using our contact page.
How we work
- Retrieval first, training later
- Scan before you train
- Code review rules do not change
How a codebase model project runs
-

Review repositories and pain points
A staff engineer shows us where current assistants fail, such as an internal framework or migration.
-

Replay changes on the baseline
Retrieval plus instructions attempt real merged changes, scored on compile, tests and engineer review.
-

Scan, check licenses, then tune
Secrets and license problems are handled first, and the base license is read before training begins.
-

Shadow period in pull requests
The model comments or drafts without merging anything, and reviewers record what they accepted or rejected.
Why Aranv for code models
We may tell you not to
If the retrieval setup passes your replay tests, we recommend staying there, since every trained model must be retrained as code moves.
Leak tests are on the exam
Planted fake keys and removed secrets become test cases, so a model that repeats them fails before it reaches an editor.
Clean splits, honest scores
Date-based splits and removal of duplicate commits stop old answers appearing in the exam, the easiest route to a flattering result.
Reviewers keep their authority
Model output enters through normal pull requests. Required approvals, code owners and your security checks stay where they are today.
Planning Train an LLM on Your Codebase?
Book a 30-minute conversation with the team that would build it.
Train an LLM on Your Codebase FAQs
-
Should we train an LLM on our code or use retrieval?
Use retrieval first. Indexing the repository and writing good instructions gives most teams more for less effort, and it stays current as code changes. Consider training only for a large private codebase, unknown internal frameworks or code that cannot leave.
-
What is a private coding assistant, and does it need training?
It is a coding assistant running on infrastructure you control, and it does not require training. An open-weight model on your servers with retrieval over your repositories may already meet the need.
-
What does code completion model training involve?
Tuning a base model on examples of your code, then testing on changes it has not seen. The work covers extracting examples from merged history, removing secrets and restricted code, and measuring suggestions in the editor, including response time.
-
Could the model leak secrets from our repository?
It could if secrets reach training. We scan the whole history, not only the current tree. Rotate any real credential we find, because removing it from training does not make it safe.
-
Will this replace code reviewers?
No. A model can produce code that compiles, passes tests and is still wrong for your system. Output goes through normal pull requests with your existing approvals, and reviewers remain accountable for what merges.
-
How do we keep a trained code model from going stale?
Keep retrieval in the loop and plan to retrain. Retrieval supplies current files while the tuned model supplies habits. Retrain after a framework change or major migration, and rerun the replay tests each time.
-
Who owns a model trained on our code?
We put ownership in the contract before work starts. Our recommended terms give you the weights, adapters, training examples, test sets and code as soon as the work is paid for, and the base model’s license keeps applying to them.

Let’s talk about your next step
Contact Aranv to discuss your workflow, current tools, and goals. Meet with our team or send an inquiry.
Aranv at a glance
- 9Years in business
- 120+Clients served
- 300+Projects delivered
- 200+Team members
What happens next
- Pick a time, or send your project details.
- We review your goals, current tools and timeline.
- You get a clear next step: a scope, plan or estimate.
Book a meeting with our team
Choose an available date and time for a 30-minute conversation about your project.
- 30 minutes
- Online video call
- Times in your time zone
Tell us about your project
Share a few details so we can discuss a useful next step.
Prefer email? sales@aranv.com