


What NLP development includes
Aranv offers NLP development services to growing US firms that receive more written text than staff can read. We build natural language processing systems that classify emails and tickets, pull fields out of documents, measure themes in feedback and search records by meaning, then write the output into your CRM, helpdesk or reports.
Natural language processing is the branch of AI that reads and writes human language. For a business it usually means four jobs: sorting text, extracting facts, summarizing and finding things again. Conversation is a fifth job, and assistants that talk with customers are covered under conversational AI development.
Large language models now handle many of these jobs with a careful prompt, and our LLM integration team connects them to your systems. For high volumes or tight latency, a smaller model trained on your labels can be cheaper and more predictable. We test both on the same sample before recommending one.
How free text becomes structured data
From messages to fields
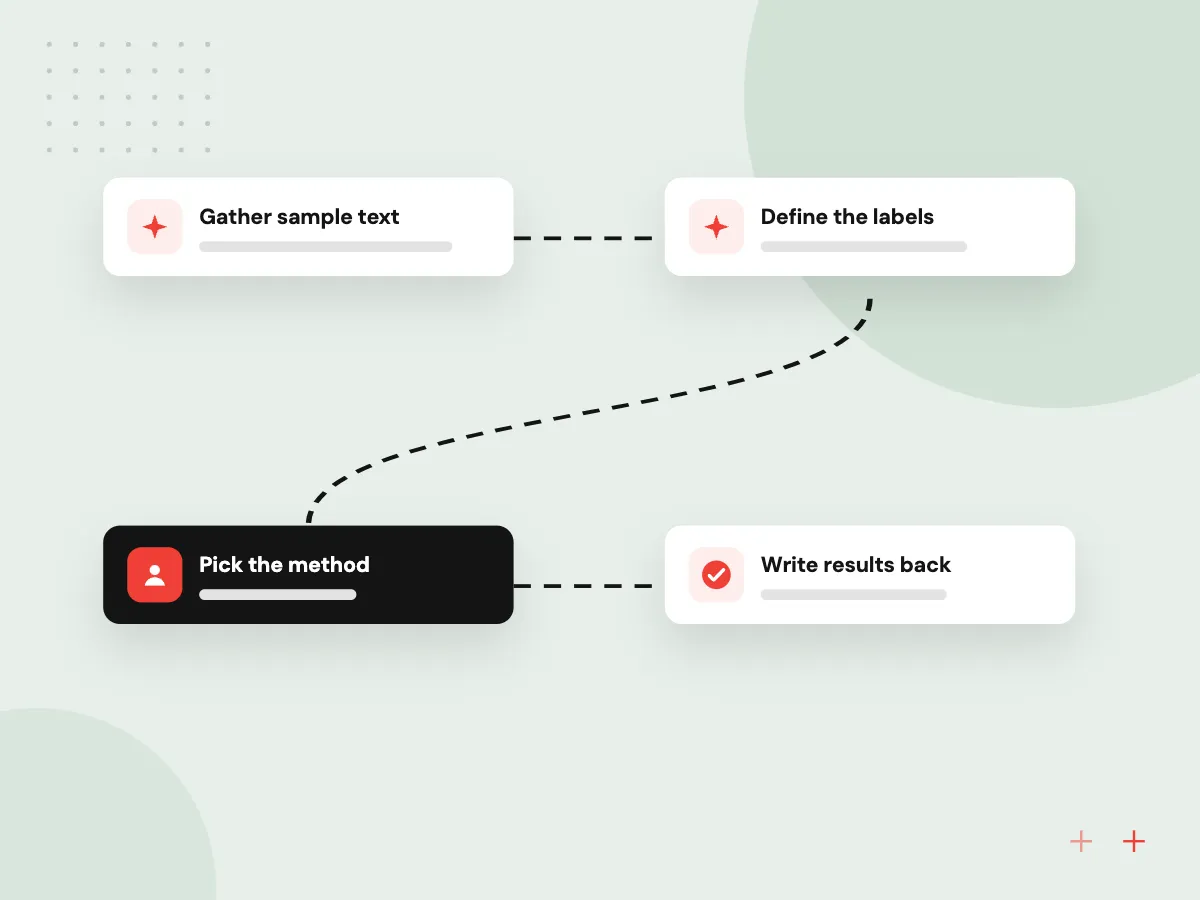
- 01 Gather sample text Emails, tickets, notes or reviews exported with the outcome staff recorded for each.
- 02 Define the labels Categories, fields and edge cases written down with the people who sort text today.
- 03 Pick the method A language model, a trained classifier or plain rules, chosen by test results.
- 04 Write results back Labels and fields land in your systems, with doubtful items queued for review.
Language models made many NLP tasks quicker to build, yet a small classifier is often cheaper at high volume.
Natural language processing services for everyday text
Most firms already hold years of text nobody has time to read twice: support threads, survey comments, call notes and contracts.
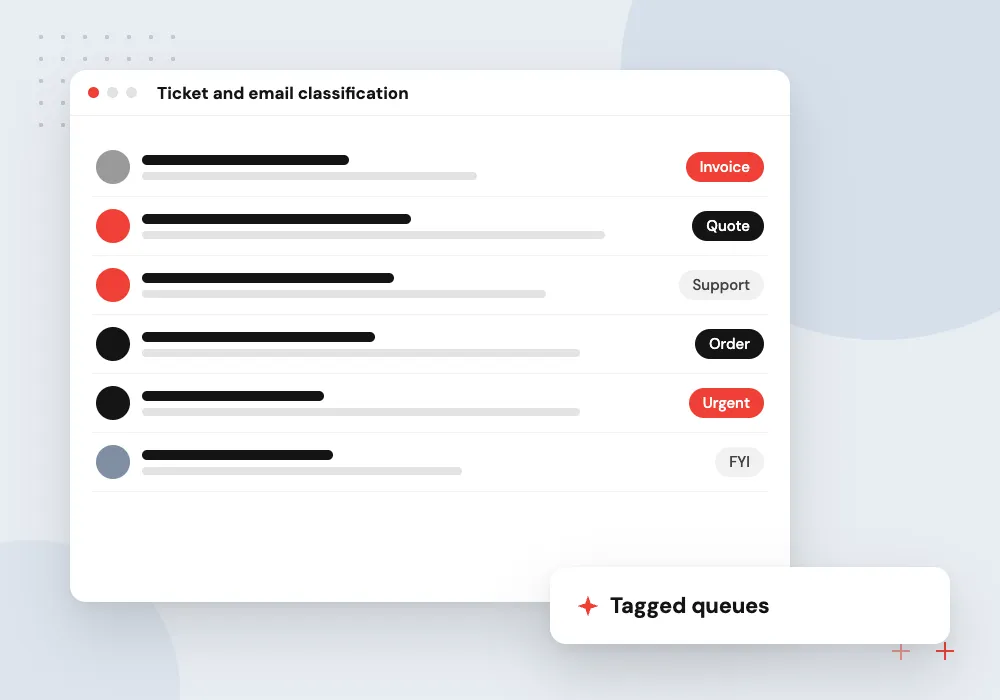
Ticket and email classification
Incoming messages tagged by topic, urgency and product so they reach the right queue without a coordinator reading each one.
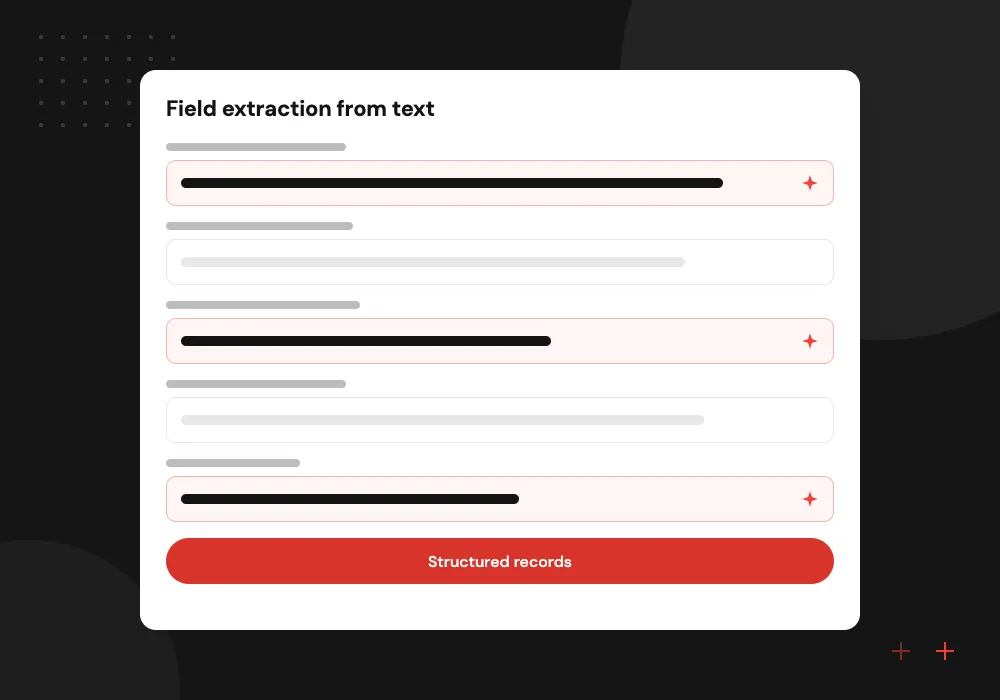
Field extraction from text
Names, dates, amounts, part numbers and clauses lifted from emails or contracts into structured fields your database can store.
Text analytics on feedback
Reviews, surveys and support notes grouped into themes and tracked by month, so managers see which complaints are growing.
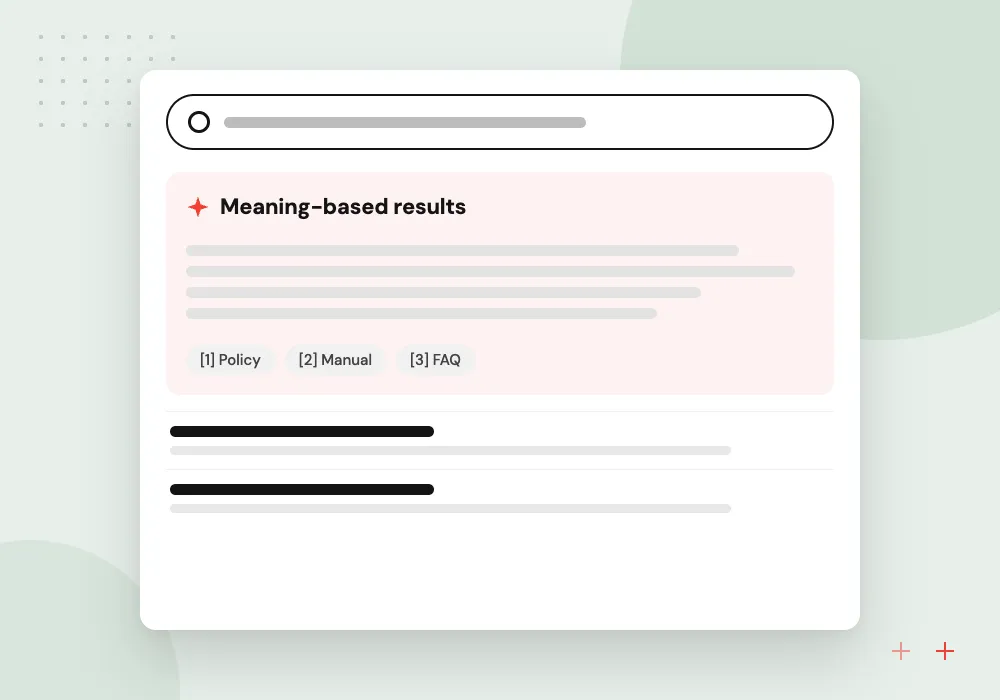
Search by meaning
Staff find past cases, policies or answers by describing the problem in their own words, even when the exact terms differ.
Classification and extraction pipelines
Most NLP value comes from turning messages into labels and fields at volume. We compare a prompted language model with a small fine-tuned classifier on your own text and choose on accuracy, speed and running cost. Plain rules still handle the cases where a pattern match is enough.
What we do
- Label set and annotation guide
- Language model versus classifier comparison
- Entity and field extraction
- Confidence score on every item
- Batch and real-time processing
Text data handling and human review
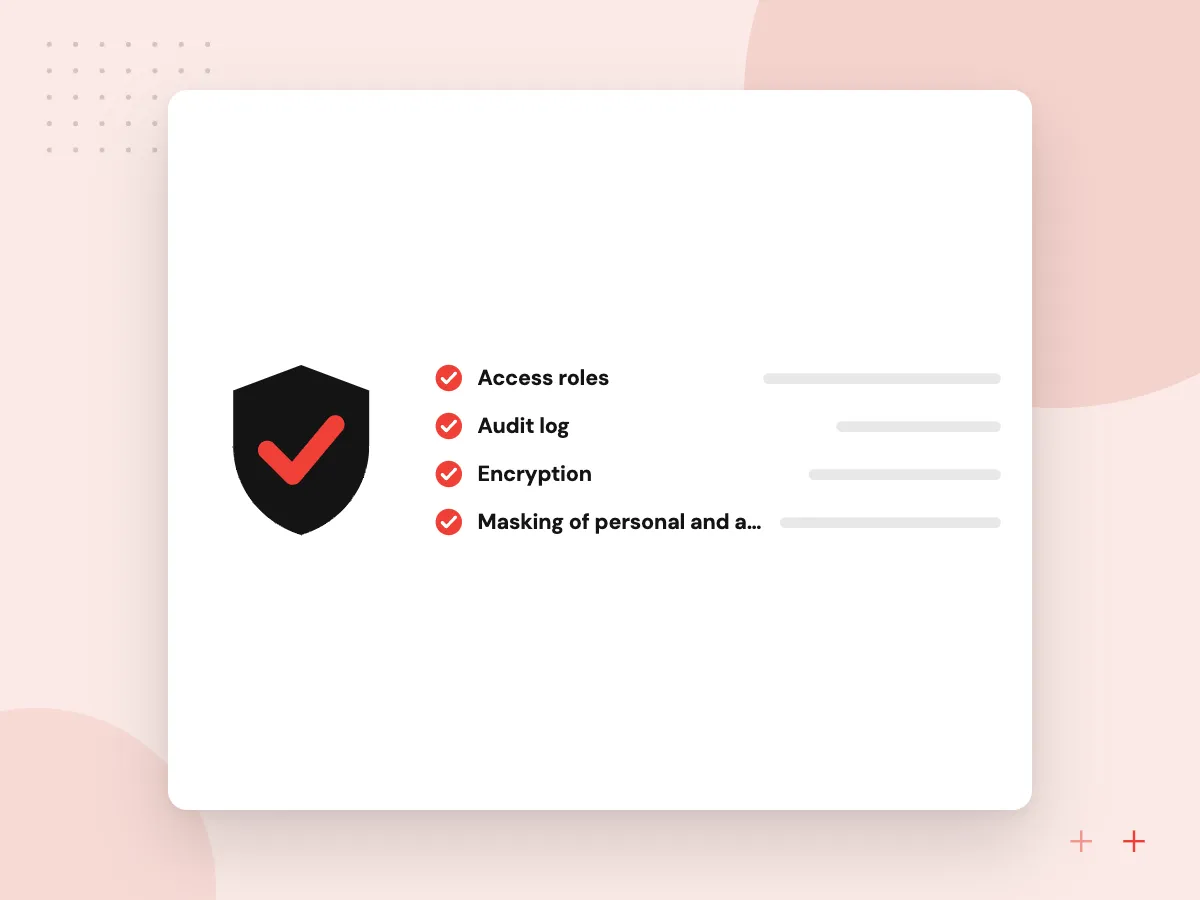
Business text often contains personal details, account numbers and health or legal information. We map where that data flows, mask or drop fields the model does not need, and keep processing in the regions you choose. Reviewers see doubtful items with the reason, and their corrections feed the next test set.
What we do
- Masking of personal and account data
- Hosting region and retention rules
- Review screen for doubtful items
- Monthly accuracy check on samples
- Log of model and prompt versions
How we approach a project
Typical projects include AI email triage, customer sentiment analysis and clause extraction from contracts. When the text sits inside scanned PDFs or photos, it first passes through OCR so the language model receives clean text.
Holding a pile of text and a decision that depends on it? A 30-minute conversation is usually enough to judge whether NLP fits. Request one through our contact page and bring a few anonymized examples.
How we work
- Labels defined by your staff
- Measured on your own text
- Doubtful items go to people
Our Process
-

Sample and label
We pull a few hundred representative messages or documents and label them with your staff to set the ground truth.
-

Compare approaches
Prompted language models, fine-tuned classifiers and rules are scored and costed on the same held-back sample.
-

Build the pipeline
Connectors read text from your inbox, helpdesk or file store, and results are written back with a confidence score.
-

Watch for drift
New products and new complaint types change the text, so we sample results monthly and update labels when categories shift.
Why Aranv for NLP work
We define labels with you
Categories and fields are written with the people who sort text today, including the awkward edge cases, so the model learns your rules rather than ours.
Method chosen by test
We do not assume a large model is needed. Each approach is scored and costed on your sample, and the cheapest one that meets the target wins.
Private text stays controlled
Personal and account details are masked before processing where possible, and hosting, retention and provider terms are agreed in writing first.
Connected to where work happens
Labels, fields and summaries are written into your helpdesk, CRM or database, so staff act on them inside tools they already use.
Planning NLP Development?
Book a 30-minute conversation with the team that would build it.
NLP development FAQs
-
What can natural language processing do for a small business?
It turns text you already have into actions or numbers: routing emails, pulling order details from messages, grouping review comments by theme or finding the right policy paragraph. The best first project is one where staff read the same kind of text many times a day.
-
Do we still need custom NLP now that general chat models exist?
Sometimes not. A general language model with a careful prompt handles many sorting and summarizing tasks well. Custom work is still needed to connect it to your systems, define your labels, test accuracy on your text, control cost at volume and handle private data correctly.
-
How accurate is text classification?
It depends on how clear your categories are. If two experienced staff often disagree about a label, a model will struggle too. We measure agreement between people first, then report accuracy per category on held-back text so you see where the model is strong and where it needs review.
-
Can NLP handle Spanish and other languages?
Current language models handle Spanish and many other widely spoken languages well, while results for less common languages vary. We test on real samples in each language you receive and can route text in unsupported languages to a bilingual staff member.
-
Where does our text go during processing?
That is agreed before the build. Text can go to a model provider under business terms you have reviewed for data use and retention, to a cloud AI service in a region you choose, or to an open model on your own servers. In every case we mask fields the model does not need.

Let’s talk about your next step
Contact Aranv to discuss your workflow, current tools, and goals. Meet with our team or send an inquiry.
Book a meeting with our team
Choose an available date and time for a 30-minute conversation about your project.
Tell us about your project
Share a few details so we can discuss a useful next step.
Prefer email? sales@aranv.com